
Importing a dataset into Python involves using specialized libraries—primarily pandas—to read structured data from files like CSV, Excel, or JSON into a DataFrame. By utilizing functions such as read_csv() or read_excel(), you can transform raw external data into a manipulatable format, enabling efficient analysis, cleaning, and visualization within your Python environment.
Prerequisites for Data Ingestion in Python
Before you begin the process of importing data, it is essential to ensure that your local environment is correctly configured. Python does not come with built-in, high-level data manipulation tools by default; these capabilities are provided by third-party libraries. The industry standard for handling tabular data is the pandas library, which is built on top of NumPy.
Setting Up Your Environment
To get started, ensure you have Python installed. By 2026, most data science workflows rely on virtual environments to manage dependencies. You should verify that you have pandas installed by running the appropriate package manager command in your terminal. If you are using a standard Python distribution, the following command is typically used:
pip install pandas
If you are working with Excel files, you will also need an engine to process them, such as openpyxl. You can install both simultaneously:
pip install pandas openpyxl
Understanding File Paths
One of the most common hurdles for beginners is the "FileNotFoundError." This occurs when Python cannot locate the file you are attempting to import. It is crucial to understand the distinction between absolute paths and relative paths. A relative path refers to a location relative to the current working directory, while an absolute path provides the complete address of the file on your machine. Using an IDE like VS Code or Jupyter Notebook helps because the "current working directory" is usually set to the root folder of your project, making relative paths much easier to manage.
Importing Common Data Formats
Data comes in various shapes and sizes. The method you choose depends entirely on the file extension and the internal structure of your dataset.
Importing CSV Files
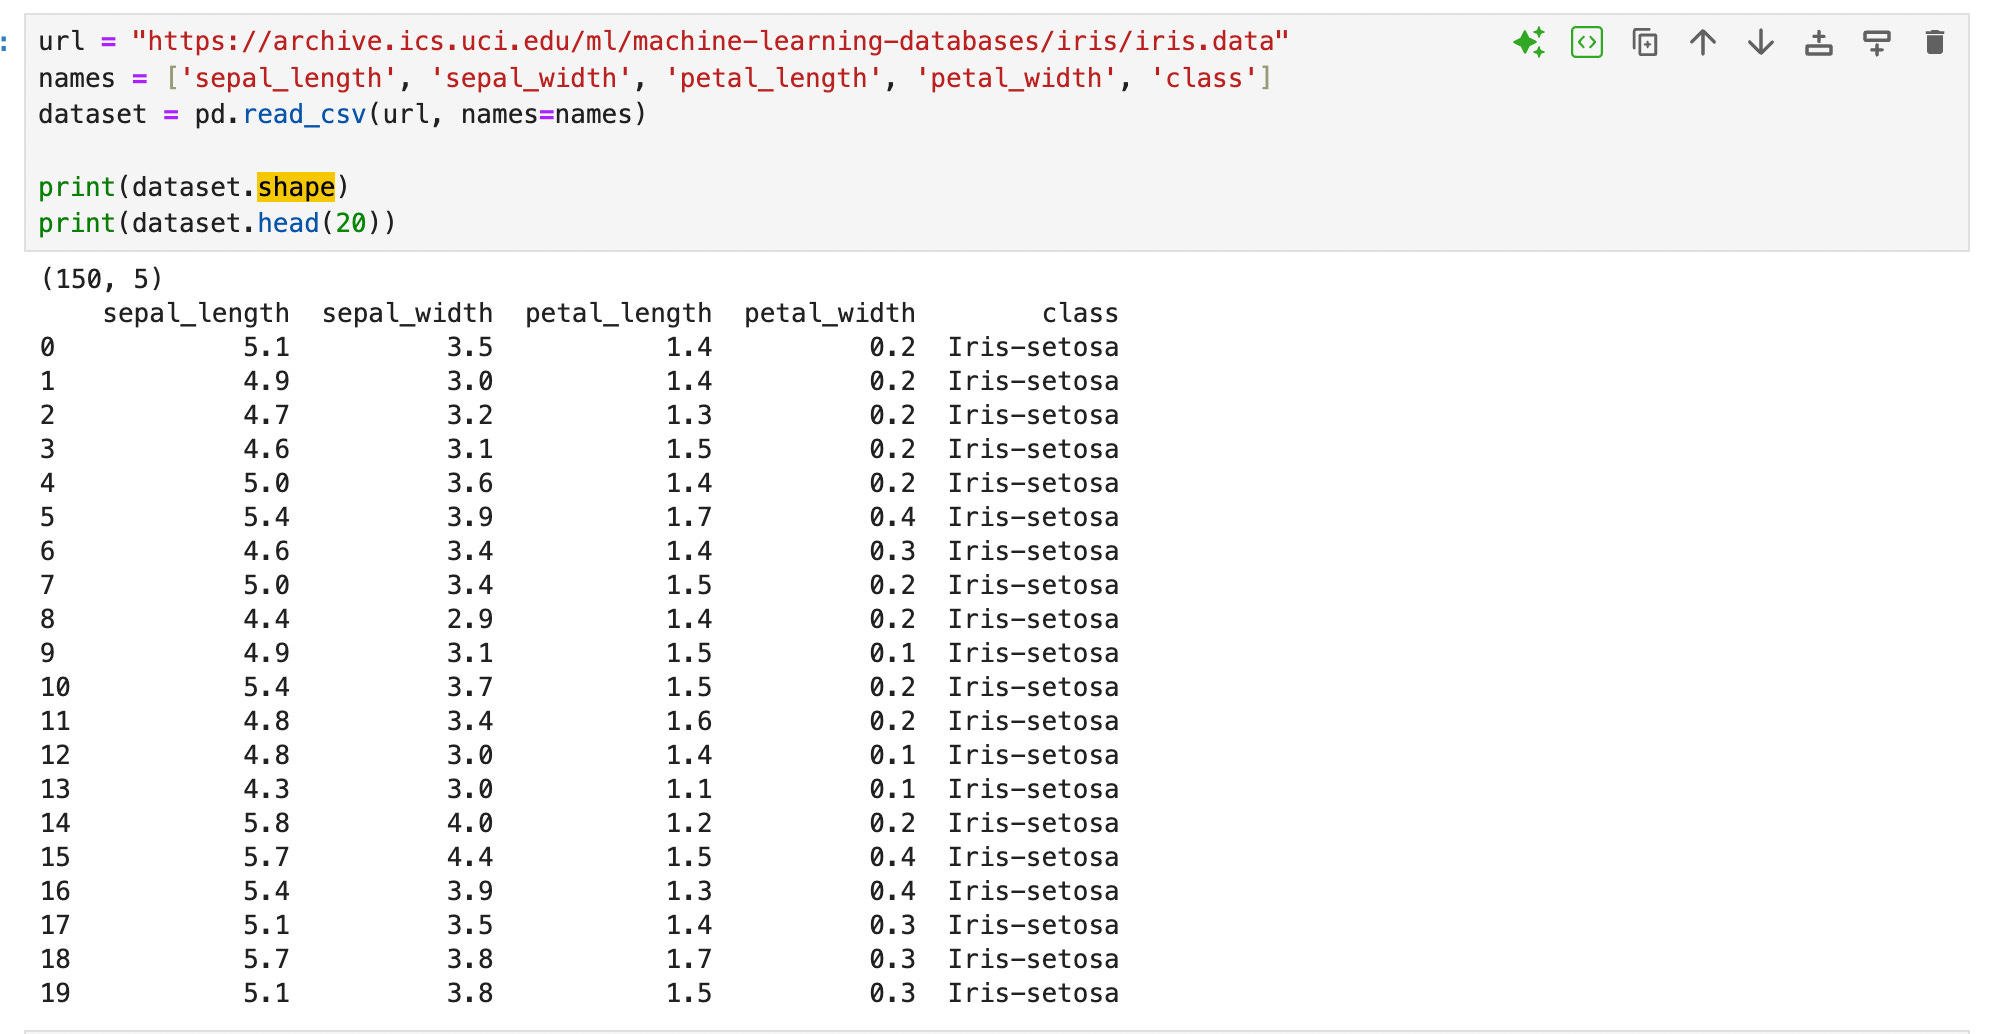
Comma-Separated Values (CSV) are the most ubiquitous format in data science. The pandas.read_csv() function is highly optimized and offers dozens of parameters to handle nuances such as custom delimiters, encoding issues, or date parsing.
When you import a CSV, pandas automatically infers the data types of your columns. For example, a column containing numeric values will be assigned an integer or float type, while a column containing text will be assigned an object type. If your dataset uses a semicolon instead of a comma, you can specify this using the sep parameter:
df = pd.read_csv('data.csv', sep=';')
Working with Excel Workbooks
Excel files are often used for sharing structured data across business departments. Using pandas.read_excel(), you can pull data from specific sheets within a workbook. If you do not specify a sheet name, pandas defaults to the first one it finds.
It is important to note that importing large Excel files can be memory-intensive. Unlike CSVs, which are text-based, Excel files are binary, requiring the library to parse the underlying XML structure, which consumes more system resources during the read operation.
Handling JSON and Other Formats
JavaScript Object Notation (JSON) is the standard for web-based data. JSON files often contain nested hierarchies, which means they do not always map perfectly to a flat, two-dimensional table. When importing JSON, you may need to use json_normalize from the pandas library to flatten nested records into a structure that a DataFrame can interpret effectively.
Comparison of Common Import Methods
Choosing the right format and method can drastically improve the performance of your data pipeline. The following table summarizes the primary import functions provided by the pandas library.
| File Format | Primary Function | Key Parameters | Best Use Case |
|---|---|---|---|
| CSV | read_csv |
sep, encoding, names |
Large, flat, simple datasets |
| Excel | read_excel |
sheet_name, header |
Business reporting, legacy data |
| JSON | read_json |
orient, lines |
API responses, web-scraped data |
| Parquet | read_parquet |
engine |
High-performance, compressed storage |
| SQL | read_sql |
con, sql |
Accessing databases directly |
Verifying the Import
Once you have successfully executed the import command, your next step is to verify the integrity of the data. Simply loading the file is not enough; you must ensure that the structure matches your expectations.
Initial Inspection Techniques
After assigning the dataset to a variable—commonly named df—you should immediately inspect the top and bottom rows using the .head() and .tail() methods. These methods provide a quick visual check of the first five and last five rows, respectively.
Beyond a visual check, use the .info() method. This is arguably the most important command after an import. It provides a summary of:
- The number of non-null entries in each column.
- The data types (Dtypes) assigned to each column.
- The total memory usage of the DataFrame.
If a column that should contain numbers is labeled as an "object" (string), this is a red flag indicating that there may be non-numeric characters hidden within the data, such as a stray currency symbol or a misplaced space.
Handling Encoding Issues
A frequent error when importing text-based files is the UnicodeDecodeError. This happens when the file encoding (such as UTF-8, Latin-1, or CP1252) does not match the encoding expected by your Python environment. If you encounter this, try specifying the encoding parameter in your read function:
df = pd.read_csv('data.csv', encoding='latin1')
Troubleshooting Common Errors
Memory Errors
If you are attempting to import a multi-gigabyte dataset, you may encounter a memory error. This occurs because the entire file is loaded into your system's RAM. To resolve this, consider using the chunksize parameter in read_csv(). This allows you to process the file in smaller, manageable segments rather than all at once.
Missing Headers
If your CSV file does not have a header row, pandas will treat the first row of data as the column names. To prevent this, use header=None. You can then provide a list of names manually using the names parameter to properly label your columns.
Date and Time Formatting
Dates are often the most difficult data type to handle. If Python imports a date column as a string, you will not be able to perform time-series analysis. You can force the conversion during the import process by utilizing the parse_dates parameter:
df = pd.read_csv('data.csv', parse_dates=['date_column_name'])
Next Steps: From Import to Analysis
Once the data is successfully loaded and verified, the real work begins. Your immediate next steps should involve cleaning the data, which includes handling missing values (using .fillna() or .dropna()), removing duplicates (.drop_duplicates()), and standardizing column formats.
By masterfully managing the import phase, you ensure that the rest of your analytical pipeline is robust, reproducible, and efficient. Remember that every dataset is unique; spend time familiarizing yourself with the raw file before jumping into complex statistical transformations.
Frequently Asked Questions
Can I import data from a URL?
Yes, you can. The pandas read_csv() and read_excel() functions accept a URL string as the file path, provided the URL points directly to the data file. Python will download the content into memory, allowing you to bypass the step of manually downloading the file to your local computer.
How do I import only a few columns?
To save memory and increase speed, use the usecols parameter. You can pass a list of column names or index positions to this parameter, and pandas will only load the specified data into the DataFrame, ignoring everything else.
What if my dataset is in a SQL database?
To import data from a database, you need to establish a connection using a library like SQLAlchemy. Once the connection is established, you can use the pd.read_sql() function. This method is significantly more secure and efficient for production environments than exporting SQL results to a CSV first.
Does the order of rows matter during import?
Generally, pandas preserves the order of rows as they appear in the source file. If your data is time-series based, this order is critical. If your data is unordered, you may want to sort the data after importing it using the .sort_values() method based on a primary identifier or timestamp.
Is it better to use CSV or Parquet?
For small to medium projects, CSV is easier to read and inspect. However, for large datasets, Parquet is superior. Parquet is a columnar storage format that is highly compressed and optimized for query speed, making it the preferred choice for big data pipelines by 2026.
Image Gallery
Select an image to open it in a new tab.
Omar Farooq
EdTech Innovation and Virtual Pedagogy Journalist
